
Found Is Testing a $200 vs $150 Shipt Sign-Up Bonus. Here's the Math
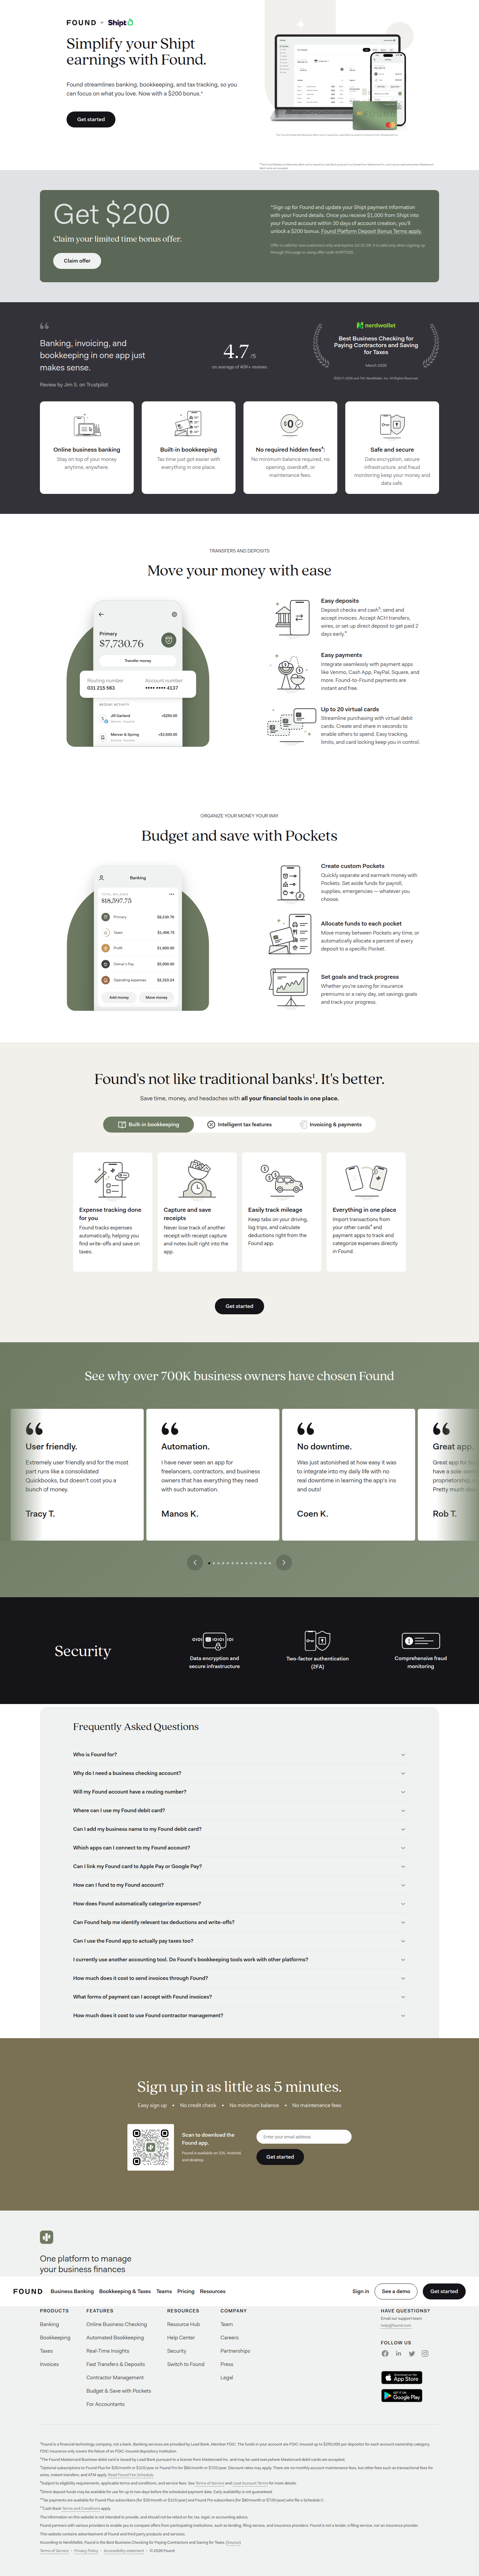
Found is running a server-side split of /shipt200 vs /shipt150, testing bonus size against CPA. Here's how to think about the incrementality math before you copy it.
Sam Lee
Data Analyst · · Updated
TL;DR
- Found (found.com) is running a live server-side A/B test detected 12 March 2026 on the URL
/shipt200. - Traffic is split between two funnel variants: a $200 bonus headline (
shipt200) and a $150 bonus headline (shipt150). - Detection method:
url_cluster_variant— routing happens server-side, not via client-side DOM swap. - Promo banner copy and FAQ block length both shift to match the bonus amount shown in the hero.
- ABWatcher analyst confidence: 90%.
- Likely hypothesis: incentive-size elasticity on driver sign-up conversion, weighed against cost per acquisition (CPA).
What did Found actually change on the page?
Found split-tested its Shipt driver acquisition landing page by routing visitors to one of two bonus-amount variants at the URL level. The hero headline, subhead, and promo banner all update in lockstep — visitors landing on the shipt200 cluster see "$200 bonus," while the shipt150 cluster sees "$150 bonus." Our vision-AI analyser also flagged a secondary, correlated change: the FAQ section length differs slightly between variants, which suggests the $200 arm may need more objection-handling copy to justify the higher headline number, or simply that the two funnels were built at different times and never fully reconciled.
This is a server-side split, not a JS-injected variant — meaning it's routed at the infrastructure layer before the page renders, not toggled client-side after load. That's a meaningfully more mature testing setup than most landing-page experiments we catch, and it rules out flicker/FOUC contamination that can quietly bias client-side test results.
Why does bonus size make a good — and risky — A/B test?
Bonus-size tests are attractive because the variable is a single line-item change, but the payoff structure is nonlinear against CPA. A $200 vs $150 offer is a 33% increase in stated incentive cost per converted driver. For the test to be worth running, the $200 arm needs to lift sign-up rate by more than 33% just to hold cost per acquisition (CPA) flat — anything less than that lift and the higher bonus is actively worse unit economics, even if raw conversion rate goes up.
Put concretely: if the $150 arm converts landing visitors to completed sign-ups at 4.0%, the $200 arm needs to hit roughly 5.3% conversion just to match CPA. If it lands at 4.5% instead, Found's cost per driver acquired rises by about 18% even though absolute conversions go up. This is the classic incentive-elasticity trap — marketers see the conversion-rate chart go up and call it a win without pulling CPA into the same view.
How much traffic do you need to trust a bonus-size result?
At typical landing-page volumes, this test needs real sample size before either arm can be called significant. Assume a baseline sign-up conversion rate of 4% and you want to detect a 15% relative lift (4.0% → 4.6%) at 80% power and 95% confidence — that requires roughly 19,000 visitors per arm (about 38,000 total), using a standard two-proportion sample size calculation. Gig-economy acquisition pages with heavy paid traffic can clear that in a week or two; organic-heavy pages can take a month or more. Until Found hits that volume, any interim readout is noise dressed as signal, and stopping early on an apparent early lead is one of the most common ways teams manufacture false wins — a caution echoed across most serious A/B testing methodology guides.
| Metric | $150 arm (baseline) | $200 arm (need to hit) |
|---|---|---|
| Bonus cost per driver | $150 | $200 |
| Required conversion lift to hold CPA flat | — | +33% relative |
| Example: baseline conv. rate | 4.0% | needs ≥5.3% |
| Sample size for 15% lift @ 80% power | ~19,000/arm | ~19,000/arm |
| Risk if lift < 33% | — | CPA rises despite more signups |
What segment-level effects should Found be watching?
Aggregate lift can mask offer sensitivity that varies sharply by traffic source and driver tenure. Paid social traffic, organic search, and referral links typically carry different price sensitivity — a $50 delta might swing a cold Facebook audience meaningfully while barely moving referral traffic that's already high-intent. If Found is pooling all traffic sources into one topline conversion number, they risk a Simpson's paradox scenario where the blended result looks flat while one channel is up 20% and another is down 10%. Any team running this playbook should slice by UTM source and by new-vs-returning visitor before declaring a winner, not after.
There's also a novelty/seasonality confound specific to gig work: driver sign-up demand is elastic to macro labor conditions (holiday season parcel volume, other platforms' concurrent promos). A bonus test run during a demand spike will look artificially strong regardless of amount, so the test window needs to be long enough to span at least one full weekly cycle, ideally two, to average out day-of-week effects in gig-worker sign-up behavior. General CRO guidance on structuring a defensible test program makes the same point about isolating one variable per test cycle — bonus amount here, not bonus amount plus banner copy plus FAQ length simultaneously, which is what the correlated FAQ change risks doing.
What's the takeaway for your own roadmap?
If you're testing incentive size on any acquisition funnel this sprint, write down the required relative lift to hold CPA flat before you launch — for Found's $150→$200 test that's +33%, not "any positive lift." Pre-register your minimum detectable effect and sample size (here, ~19K/arm for a 15% lift at 80%/95%), commit to a full multi-week window to avoid day-of-week and demand-spike confounds, and slice results by traffic source before you read the topline number. A dollar-amount test is one of the cleanest single-variable experiments you can run — but only if the guardrail metric is CPA, not conversion rate alone.
Common questions
What does "server-side split" mean and why does it matter here?
It means Found routes visitors to the $200 or $150 variant at the server/infrastructure level before the page loads, rather than swapping content client-side with JavaScript. This avoids flicker effects and client-side bias, and it's a signal the test is run through a more mature experimentation stack.
How big a lift does the $200 bonus need to beat the $150 bonus on unit economics?
Since $200 is a 33% higher cost per acquired driver than $150, the $200 arm needs at least a 33% relative lift in conversion rate just to hold cost per acquisition flat. Any smaller lift means the $200 offer converts more people but at a worse CPA.
How long should a bonus-amount A/B test run before trusting the result?
Long enough to clear the required sample size and span full weekly cycles — for a 15% lift detection at 80% power and 95% confidence off a 4% baseline, that's roughly 19,000 visitors per arm, ideally spread across two or more full weeks to average out day-of-week and demand-spike effects.
Could the FAQ length difference between variants be biasing the test?
Possibly — if the $200 variant has more objection-handling FAQ copy, any conversion difference could be partly attributable to page content rather than bonus amount alone, muddying attribution. A clean test isolates one variable; Found should confirm FAQ parity across arms before trusting the readout.
Is a single-variant win enough to declare the $200 offer the winner?
No. A single topline win without a confidence interval, segment breakdown by traffic source, and a CPA-adjusted view is not decision-grade evidence — it's a data point that needs replication and guardrail-metric confirmation before rollout.
Read next
More from the ABWatcher blog
Nov 22, 2026
Snake River Farms Tests a $25-Off Popup on Its Ad Landing Page
We caught Snake River Farms split-testing an email-capture form and $25-off modal on its landing page. Here's the math on what it would take to call a winner.
Nov 21, 2026
Snake River Farms Tests Mid-Page Email Capture on Its Ad Landing Page
SRF is A/B testing a mid-page lead-capture block and a $25-off popup against a simpler hero-only promo banner on its paid landing page, detected 2024 week-over-week.
Nov 20, 2026
Attio Is Testing a New Tier, Higher Prices, and a New Pitch
Attio is running a live pricing page test with a new $1,000 "Ultra" tier, higher Plus/Pro prices, and a new headline — here's what we caught and what it means.
Nov 19, 2026
Found Quietly Tested a 25% Price Cut on Its Pricing Page
We caught Found running a live pricing A/B test with an annual billing toggle that drops Found Plus from $35 to $26.25/mo. Here's what changed and why it matters.
Nov 8, 2026
Astro Proves "Zero Lock-In" With a Live Code Demo, Not a Claim
Astro's homepage replaces a trust badge row with a working, clickable framework demo — here's the hierarchy and interaction design behind it, detected 60% rare on astro.build.
Nov 7, 2026
Basecamp's Big Numbers: Why Hyper-Precise Stats Beat Vague Social Proof
Basecamp's homepage swaps "trusted by thousands" for 1.7 billion to-dos and 5 petabytes of data. We break down why precision beats vagueness as social proof — and how to test it.
From the glossary
Vocabulary the article uses. See all terms →
- Shrinkage Estimator— A statistical adjustment that pulls noisy per-variant or per-segment estimates toward an overall average to reduce overfitting to randomness.
- Flicker Test— A diagnostic check to confirm whether users briefly see the original page before a variant renders in client-side experiments.
- Pre-Experiment Bucketing Audit— A review process confirming users are being randomly and evenly assigned to experiment variants before launch.
- Above-Fold Exclusion Rule— A test-design rule that deliberately prevents changes to above-the-fold elements so an experiment isolates below-the-fold effects.
- Flicker-Free Testing— A technical setup that prevents users from briefly seeing the original page before a test variant loads.
- Orthogonal Test Design— A test structure where multiple variables are changed independently so their individual effects can be measured without interference.
See more like this
ABWatcher catches A/B tests like this across 1,000+ brands.
Watch live experiments at 1,000+ high-converting brands, complete with hypothesis and takeaway. 7 days of Pro, free, no card, then Free forever for ten watched companies.