
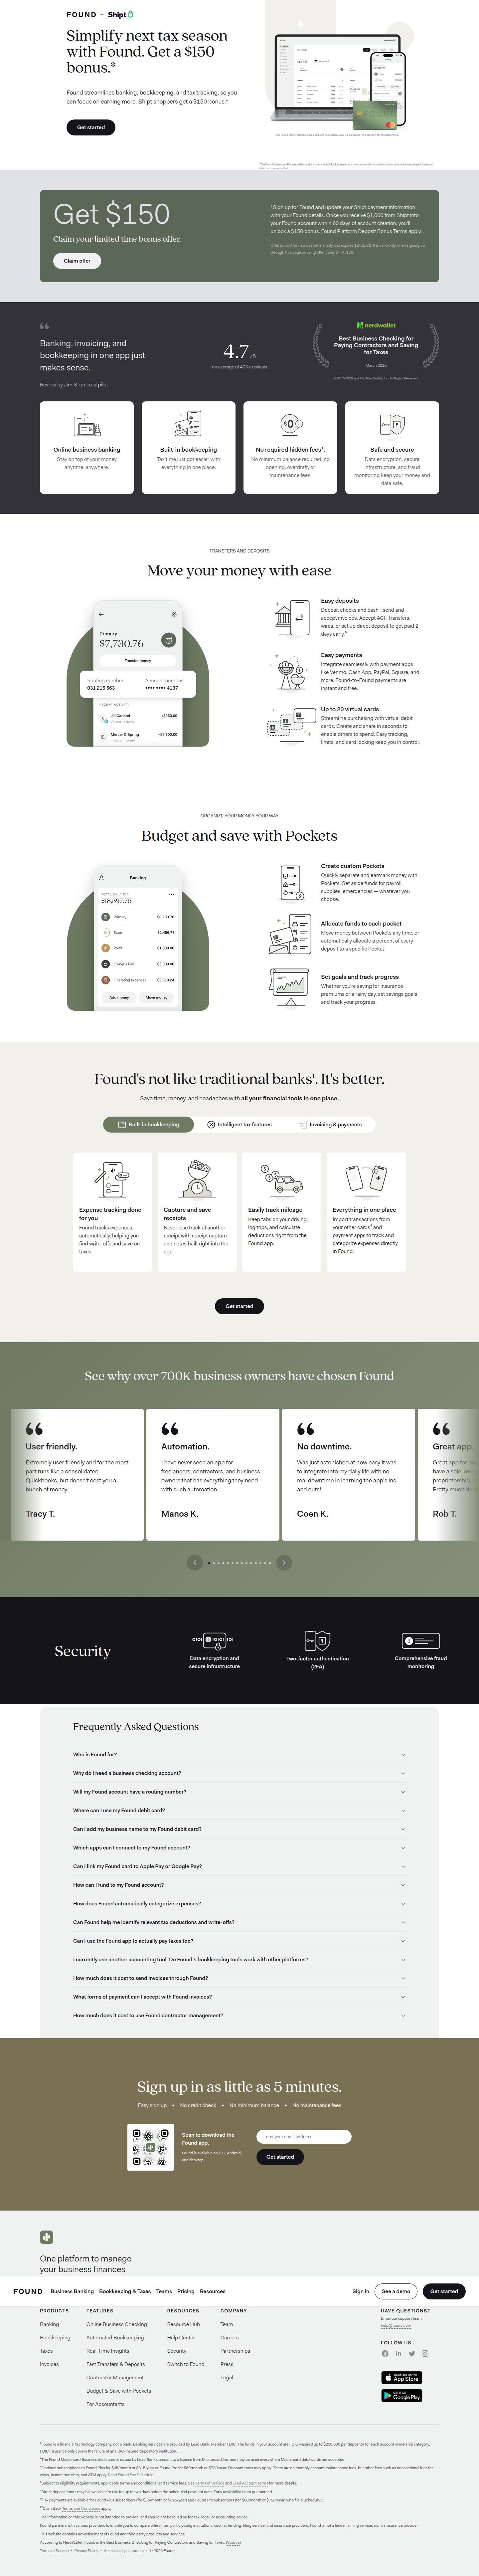
Found Is A/B Testing Its Sign-Up Bonus: $150 vs $100
Found is running a server-side split test on bonus amount — $150 vs $100 — via two dedicated landing pages. Here's what it means for your incentive strategy.
Diego Hernandez
Growth Marketer · · Updated
TL;DR
- Found (found.com) is running a live split test on sign-up bonus amount, detected 90% confidence via URL cluster analysis.
- Two dedicated landing pages: found.com/shipt150 ($150 bonus) vs found.com/shipt100 ($100 bonus).
- Split happens server-side — visitors get routed before the page even renders, not via client-side JS swap.
- Headline and banner copy match across both variants, isolating bonus amount as the single variable.
- Hypothesis: find the lowest bonus that still converts, not the highest bonus that converts best.
- Detection method: url_cluster_variant, flagged on found.com's Shipt-partner acquisition funnel.
What exactly did Found change?
Found split traffic to two nearly identical landing pages that differ only in the bonus dollar amount and its mirrored copy. One cohort lands on /shipt150 and sees a $150 sign-up bonus. The other lands on /shipt100 and sees $100. Headlines, banner treatment, and layout are otherwise matched — this is a clean single-variable test, not a redesign wearing a discount sticker.
That matters. A lot of "bonus" tests we catch in the wild bundle in new imagery, new CTAs, new trust badges. This one didn't. Found isolated the variable that actually costs them money: the offer size itself.
Why route this server-side instead of with a client-side tool?
Server-side routing sends each visitor to a fully separate URL before any page loads, avoiding flicker and letting the test scale cleanly across paid traffic sources. Client-side A/B tools (think Optimizely widgets or a WordPress plugin swapping a hero div) render the default page first, then flash in the variant. For a paid acquisition landing page — likely fed by Shipt-affiliated influencer or referral traffic — that flicker kills trust and tanks page speed scores. Found skipped that problem entirely by pre-baking two static pages and splitting at the routing layer.
It's the same instinct behind most serious CRO infrastructure: the simpler your test looks to the visitor, the more reliable your data. VWO's guide on A/B testing makes the same point — the cleanest tests are the ones where the visitor never knows a test is happening.
What's the actual hypothesis behind $150 vs $100?
Found is testing incentive elasticity — whether a smaller bonus can hit close to the same conversion rate at meaningfully lower payout cost. This isn't really a "which number converts better" test. Everyone assumes $150 wins on raw conversion rate. The real question Found is answering: does $150 convert enough better than $100 to justify paying out an extra $50 per sign-up, at scale, across however many thousand new users this funnel drives per month?
That's a margin question dressed up as a growth question. If $100 converts at, say, 90% of the rate of $150, Found pockets a 33% reduction in acquisition cost for a 10% conversion hit. That math wins most of the time unless your funnel is volume-constrained.
How does this compare to how most teams test incentives?
Most teams either guess at a bonus number once and never revisit it, or they A/B test creative around a fixed bonus instead of testing the bonus itself.
| Approach | What's tested | What it reveals |
|---|---|---|
| Found's approach | Bonus amount ($150 vs $100), matched copy | True price elasticity of the incentive |
| Typical DTC test | Headline/CTA copy, fixed discount | Messaging effectiveness, not offer economics |
| "Set and forget" | Nothing — bonus picked once at launch | Nothing — leaves margin or conversion on the table |
Testing the number itself is rarer than it should be, because it requires finance and growth to agree on what "success" means before the test even ships. Most teams don't have that conversation until after a growth lead has already shipped five headline variants. Contentful's rundown on CRO frames this well: the highest-leverage tests are the ones tied directly to a business lever, not just a UX tweak.
What should you steal from this test?
Test the number before you test the noun. If you're running an incentive-based acquisition funnel — referral bonuses, sign-up credits, cashback offers — the dollar amount is a bigger lever than your headline will ever be. Found didn't touch imagery or CTA copy. They touched the one variable tied directly to unit economics.
Second takeaway: use server-side splits for anything running on paid or partner traffic where page-load flicker or speed hits would bias your data. Client-side tools are fine for internal experimentation on organic traffic. They're a liability on a cold acquisition page where every millisecond of load time is competing against your CPA.
Third: build the margin math into the test plan before launch, not after you see the conversion delta. Know your breakeven elasticity ratio going in, so a "close but not quite as good" result doesn't get treated as a loss when it's actually a win on cost.
Common questions
What page type was this test found on?
It was found on a landing page, specifically Found's Shipt-partner acquisition funnel at found.com/shipt150 and found.com/shipt100. Both pages target new sign-ups being routed in from what appears to be a Shipt-affiliated referral or co-marketing channel, with the bonus amount as the primary variable under test.
How confident is the detection?
The analyst confidence on this detection is 90%, based on a url_cluster_variant method that identified two structurally matched pages differing primarily in bonus amount and matching copy. High confidence reflects the clean one-variable setup and consistent server-side routing pattern observed across sessions.
Why test bonus amount instead of creative?
Bonus amount ties directly to acquisition cost and margin, while creative mostly affects click-through and message match. Testing the dollar figure answers a P&L question — what's the cheapest incentive that still hits target conversion — rather than a design question about which headline resonates more.
Is server-side testing better than client-side for this use case?
For paid or partner-driven landing pages, yes — server-side avoids the rendering flicker and page-speed penalty that client-side JS swaps introduce, which is critical when every visitor is a paid acquisition cost. Client-side tools remain fine for lower-stakes, higher-traffic organic pages where speed sensitivity is lower.
What should other growth teams do this sprint?
Audit any incentive-based funnel — referral bonuses, trial credits, cashback — and check whether you've ever actually tested the dollar amount versus just testing copy around a fixed number. If not, that's a higher-leverage test than your next headline variant, and it's overdue.
Read next
More from the ABWatcher blog
Nov 22, 2026
Snake River Farms Tests a $25-Off Popup on Its Ad Landing Page
We caught Snake River Farms split-testing an email-capture form and $25-off modal on its landing page. Here's the math on what it would take to call a winner.
Nov 21, 2026
Snake River Farms Tests Mid-Page Email Capture on Its Ad Landing Page
SRF is A/B testing a mid-page lead-capture block and a $25-off popup against a simpler hero-only promo banner on its paid landing page, detected 2024 week-over-week.
Nov 20, 2026
Attio Is Testing a New Tier, Higher Prices, and a New Pitch
Attio is running a live pricing page test with a new $1,000 "Ultra" tier, higher Plus/Pro prices, and a new headline — here's what we caught and what it means.
Nov 19, 2026
Found Quietly Tested a 25% Price Cut on Its Pricing Page
We caught Found running a live pricing A/B test with an annual billing toggle that drops Found Plus from $35 to $26.25/mo. Here's what changed and why it matters.
Nov 8, 2026
Astro Proves "Zero Lock-In" With a Live Code Demo, Not a Claim
Astro's homepage replaces a trust badge row with a working, clickable framework demo — here's the hierarchy and interaction design behind it, detected 60% rare on astro.build.
Nov 7, 2026
Basecamp's Big Numbers: Why Hyper-Precise Stats Beat Vague Social Proof
Basecamp's homepage swaps "trusted by thousands" for 1.7 billion to-dos and 5 petabytes of data. We break down why precision beats vagueness as social proof — and how to test it.
From the glossary
Vocabulary the article uses. See all terms →
- Shrinkage Estimator— A statistical adjustment that pulls noisy per-variant or per-segment estimates toward an overall average to reduce overfitting to randomness.
- Flicker Test— A diagnostic check to confirm whether users briefly see the original page before a variant renders in client-side experiments.
- Pre-Experiment Bucketing Audit— A review process confirming users are being randomly and evenly assigned to experiment variants before launch.
- Above-Fold Exclusion Rule— A test-design rule that deliberately prevents changes to above-the-fold elements so an experiment isolates below-the-fold effects.
- Flicker-Free Testing— A technical setup that prevents users from briefly seeing the original page before a test variant loads.
- Orthogonal Test Design— A test structure where multiple variables are changed independently so their individual effects can be measured without interference.
See more like this
ABWatcher catches A/B tests like this across 1,000+ brands.
Watch live experiments at 1,000+ high-converting brands, complete with hypothesis and takeaway. 7 days of Pro, free, no card, then Free forever for ten watched companies.