
Buffer Is A/B Testing Its Hero Subheadline — Here's What It Means
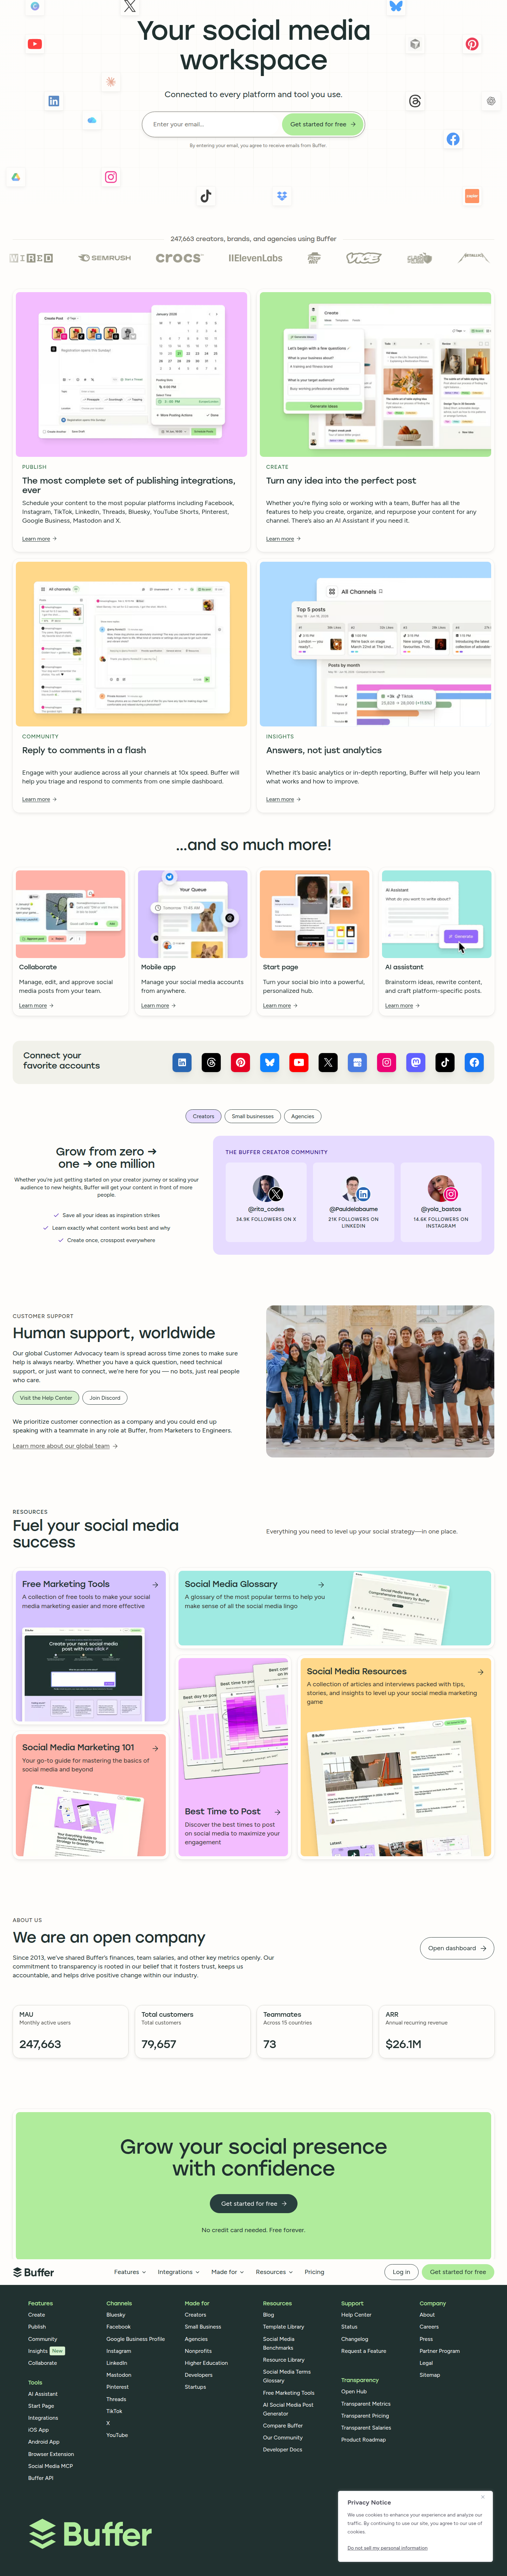
Buffer is running a live A/B test on its homepage hero subheadline, split-testing platform breadth vs. workflow-integration messaging. Here's what we detected and what to do with it.
Jordan Reeves
Founder & Operator · · Updated
TL;DR
- Detected 85% confidence live A/B test on buffer.com hero subheadline, method: vendor_sdk_active.
- Variant A (visits 1, 3, 4, 5): "Connected to every platform and tool you use."
- Variant B (visits 6, 7): "Works with every platform you post to, and plugs into your favorite tools."
- Split confirmed across both Chrome and Firefox, ruling out a rendering artifact.
- Test surface: homepage hero, the single highest-traffic, highest-stakes real estate on buffer.com.
- Hypothesis: Buffer is testing whether "platform breadth" or "workflow integration" framing drives more signups.
What exactly did Buffer change?
Buffer split-tested two subheadline variants directly under its homepage hero headline, keeping everything else on the page constant. Variant A reads "Connected to every platform and tool you use," a compact, breadth-first claim. Variant B reads "Works with every platform you post to, and plugs into your favorite tools," a longer line that separates the social-platform promise from the tool-integration promise into two distinct clauses.
That's a subtle but deliberate copy fork. Variant A compresses everything into one noun phrase — platforms and tools are treated as the same category of "connection." Variant B slows down and gives each idea its own verb: you post to platforms, you plug into tools. It's more words, but it's also more specific, and specificity is usually what's being tested for when a team splits a single sentence this precisely.
How do we know this is a real test and not a rendering bug?
The variant split appears on both Chrome and Firefox, which rules out browser-specific rendering as the explanation. When we see two different strings on the same DOM position, the first thing we check is whether it's a browser quirk, a cached asset, or a CDN edge case serving stale copy. Here, both variants of the subheadline showed up across both browser engines in our visit sample — Variant A on visits 1, 3, 4, and 5; Variant B on visits 6 and 7, each mixing Chrome and Firefox. That pattern is the fingerprint of a genuine cookie- or user-keyed split test, not a caching artifact. It's the kind of cross-checking that separates a confident detection from a guess, and it's why we log detection method (vendor_sdk_active) alongside confidence score rather than just reporting "we saw two versions."
Why would Buffer test this specific sentence?
Buffer's core positioning tension is breadth versus depth: they want to be known as "works everywhere" and "fits into how you already work" at the same time, and a single subheadline can't fully carry both without becoming a run-on. Variant A bets that visitors just want reassurance of breadth — a fast, low-friction scan that says "yes, we support your stuff." Variant B bets that separating "platforms you post to" from "tools you use" makes the value clearer to a visitor who's mid-comparison between Buffer and a competitor, because it names two distinct buying criteria instead of blurring them into one.
This is a smaller, quieter version of the hero tests we see across the category. Casey Hill's breakdown of Ramp's homepage hero notes that Buffer and Rippling have both tested into — and kept — embedded capture forms on their hero, which tells you these teams are running continuous experimentation on the highest-traffic section of the site, not just one-off copy tweaks. A subheadline split like this one is consistent with a team that treats the hero as a permanent test bed rather than a "ship it and move on" asset.
What does the research say about testing hero copy like this?
Hero copy tests are one of the most common and highest-leverage experiment categories, but wording precision matters more than volume of change. Optimizely's list of A/B testing ideas treats hero-section messaging as a top-tier test category precisely because it's the first thing every visitor reads, meaning small wording shifts compound across 100% of homepage traffic. But precision cuts both ways — Splitbase's writeup of a Dressipi hero test is a useful caution: they rewrote a headline into more casual, on-brand language and saw no movement in conversion at all. Not every "smarter" sentence wins. The lesson isn't "always test hero copy," it's "test it, but don't assume the more thoughtful variant is the winner — let the data decide."
What should a small team take from this?
Quick comparison of the two variants:
| Variant A | Variant B | |
|---|---|---|
| Word count | 8 words | 14 words |
| Structure | Single clause | Two clauses (post to / plug into) |
| Claim type | Breadth (platforms = tools) | Breadth + specificity (platforms vs. tools separated) |
| Visits observed | 1, 3, 4, 5 | 6, 7 |
| Likely optimization target | Scan speed, low friction | Clarity for comparison shoppers |
If you're a product or growth team with limited test bandwidth this sprint, the takeaway isn't "copy Buffer's subheadline." It's that a team with Buffer's traffic still finds it worth testing an eight-word sentence fork on the highest-visibility spot on the site. That's a signal about where marginal gains still live even for a mature product: not in redesigns, but in how precisely you name what you do in the first two seconds of a visit.
Common questions
Is Buffer's hero subheadline test still live?
As of this detection on the dates sampled, both variants were actively serving to different visit cookies, split evenly across browser engines. We treat vendor_sdk_active detections as live until we stop seeing the split across subsequent crawls, at which point we log a winner based on which variant persists.
Why does browser-engine overlap matter for confirming an A/B test?
If a copy difference only ever appeared on one browser, it could be a rendering quirk, extension interference, or a stale cache rather than an intentional test. Seeing both variants on both Chrome and Firefox confirms the split is cookie- or session-keyed, which is the hallmark of a real, vendor-run experiment.
What's the difference between "platform breadth" and "workflow integration" messaging?
Platform breadth messaging emphasizes how many networks or channels a tool supports, answering "will this work with what I already use?" Workflow integration messaging emphasizes how a tool fits into daily habits and adjacent software, answering "will this fit how I already work?" Buffer's two variants map almost exactly onto this distinction.
Should smaller teams test hero subheadlines like this?
Yes, but only if you have enough homepage traffic to reach statistical confidence within a reasonable window, since hero copy differences tend to produce small effect sizes. Contentful's CRO guide recommends prioritizing high-traffic, high-visibility elements exactly like this one when test velocity is limited.
Did the more specific variant (B) definitely win?
We don't know yet from this detection alone — confidence on the test's existence is 85%, but we haven't logged a resolution. Historical hero tests, like Dressipi's documented case, show that more specific or "smarter" copy doesn't always outperform the simpler original, so it's worth tracking the resolution rather than assuming.
What I would actually do next
If your team is choosing between two bets this sprint, don't spend it rewriting your hero into something clever — spend it forking your subheadline into exactly two versions that each stake out a different claim (breadth vs. specificity, like Buffer did), ship it to your existing traffic, and give it two weeks before you touch anything else on the page. The hero is the one piece of real estate every visitor sees; a one-sentence fork there will teach you more about your positioning than a full redesign will.
Read next
More from the ABWatcher blog
Nov 22, 2026
Snake River Farms Tests a $25-Off Popup on Its Ad Landing Page
We caught Snake River Farms split-testing an email-capture form and $25-off modal on its landing page. Here's the math on what it would take to call a winner.
Nov 21, 2026
Snake River Farms Tests Mid-Page Email Capture on Its Ad Landing Page
SRF is A/B testing a mid-page lead-capture block and a $25-off popup against a simpler hero-only promo banner on its paid landing page, detected 2024 week-over-week.
Nov 20, 2026
Attio Is Testing a New Tier, Higher Prices, and a New Pitch
Attio is running a live pricing page test with a new $1,000 "Ultra" tier, higher Plus/Pro prices, and a new headline — here's what we caught and what it means.
Nov 19, 2026
Found Quietly Tested a 25% Price Cut on Its Pricing Page
We caught Found running a live pricing A/B test with an annual billing toggle that drops Found Plus from $35 to $26.25/mo. Here's what changed and why it matters.
Nov 8, 2026
Astro Proves "Zero Lock-In" With a Live Code Demo, Not a Claim
Astro's homepage replaces a trust badge row with a working, clickable framework demo — here's the hierarchy and interaction design behind it, detected 60% rare on astro.build.
Nov 7, 2026
Basecamp's Big Numbers: Why Hyper-Precise Stats Beat Vague Social Proof
Basecamp's homepage swaps "trusted by thousands" for 1.7 billion to-dos and 5 petabytes of data. We break down why precision beats vagueness as social proof — and how to test it.
From the glossary
Vocabulary the article uses. See all terms →
- Shrinkage Estimator— A statistical adjustment that pulls noisy per-variant or per-segment estimates toward an overall average to reduce overfitting to randomness.
- Flicker Test— A diagnostic check to confirm whether users briefly see the original page before a variant renders in client-side experiments.
- Pre-Experiment Bucketing Audit— A review process confirming users are being randomly and evenly assigned to experiment variants before launch.
- Above-Fold Exclusion Rule— A test-design rule that deliberately prevents changes to above-the-fold elements so an experiment isolates below-the-fold effects.
- Flicker-Free Testing— A technical setup that prevents users from briefly seeing the original page before a test variant loads.
- Orthogonal Test Design— A test structure where multiple variables are changed independently so their individual effects can be measured without interference.
See more like this
ABWatcher catches A/B tests like this across 1,000+ brands.
Watch live experiments at 1,000+ high-converting brands, complete with hypothesis and takeaway. 7 days of Pro, free, no card, then Free forever for ten watched companies.