
Attio Is A/B Testing Its Pricing Page — Here's What Changed
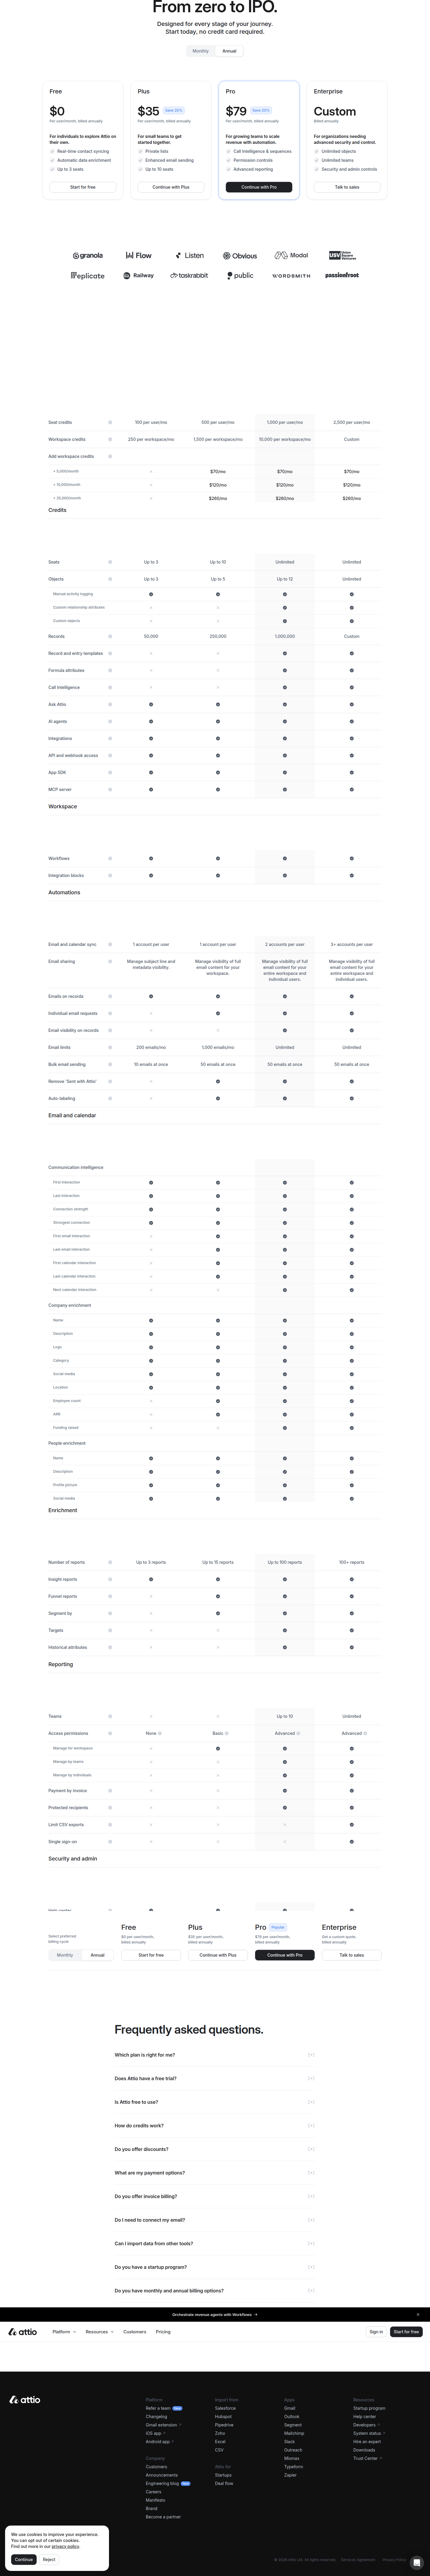
Attio is running a live pricing test with two different price points and feature limits per tier. Here's what we caught and what it means for your own pricing roadmap.
Diego Hernandez
Growth Marketer · · Updated
TL;DR
- Detected 85% confidence pricing test at attio.com/pricing via week-over-week Safari diff.
- Plus plan priced at $29 in one version, $35 in the other.
- Pro plan priced at $69 in one version, $79 in the other.
- Feature table structure differs: a "Seats" row and "MCP server" row appear in only one variant.
- "Objects" limits per plan also differ between the two versions.
- Same browser, same page, two different price architectures — this is an active test, not a caching glitch.
What did ABWatcher actually catch on Attio's pricing page?
Two Safari visits to the same URL rendered two structurally different pricing tables with different numbers. Our vision-AI analyser flagged it as a week-over-week diff: identical page layout and branding, but Plus jumped between $29 and $35, and Pro moved between $69 and $79. That's not a rounding error or a stale CDN cache — that's two live price points being served to different sessions.
The feature tables weren't identical either. One version included a "Seats" row and an "MCP server" row that simply didn't exist in the other. "Objects" limits — a core primitive in Attio's CRM data model — also varied by version. That's a bigger deal than a price tweak. It means Attio isn't just testing "what number should be on the button." It's testing what the plan includes.
Why does Attio testing both price and feature limits matter more than a simple price test?
Testing feature allowances alongside price means Attio is optimizing the full value equation, not just the number customers see. Most pricing tests we catch are cosmetic — a badge, a "Most Popular" tag, a strikethrough discount. This one touches the actual unit economics of what a seat gets you.
Bundling a seat-limit change with a price change is a smarter test design than isolating price alone, because willingness to pay is anchored to perceived value, not price in a vacuum. If Attio drops "MCP server" access from the cheaper variant, a $29 Plus plan that excludes it isn't directly comparable to a $35 Plus plan that includes it. They're testing two different products, not two labels on the same one.
This lines up with what we'd expect from a team that just posted an open growth marketing req tasked explicitly with owning pricing-page performance. Someone at Attio has "optimize pricing conversion" as a KPI right now. This test is very likely that person's fingerprints.
What do the two pricing variants actually look like side by side?
Here's the structural diff we logged between the two Safari sessions:
| Element | Variant A | Variant B |
|---|---|---|
| Plus plan price | $29 | $35 |
| Pro plan price | $69 | $79 |
| "Seats" row in feature table | Absent | Present |
| "MCP server" row | Absent | Present |
| "Objects" limit | Lower tier | Higher tier |
| Page structure/layout | Identical | Identical |
The delta is roughly 20% on Plus and 15% on Pro — meaningful enough to move revenue per account, not so large it should tank conversion outright. That's a classic sign of a team that's tested pricing before and knows not to swing for the fences on the first pass.
Worth noting: third-party trackers have already picked up conflicting numbers on Attio's public pricing. One review site cites Attio at $29 and $69 per seat as of early 2026, while another independent review references per-seat pricing with credit-based AI usage without locking in a specific figure. That inconsistency across sources is itself evidence the test has been live long enough to get scraped mid-experiment.
Is testing feature limits alongside price risky for a CRM at Attio's stage?
Yes, but it's a controlled risk if the team ships fast and kills losers quickly. Attio is post-Series-B, scaling seat-based revenue, and needs pricing precision more than most early-stage tools. Getting Plus wrong by $6/seat across thousands of seats compounds fast — in either direction. Same with gating something like MCP server access, which matters disproportionately to technical buyers evaluating Attio against Salesforce or HubSpot on integration depth.
The upside of testing bundled price+feature variants: you learn willingness-to-pay and feature demand in one motion instead of running two sequential tests. The downside: attribution gets messier. If conversion moves, is it the price or the missing seat row? Teams doing this well pair the test with clear event tracking so they can decompose the lift, not just eyeball the topline number. This is the exact discipline CRO practitioners point to as the difference between one-off tests and compounding programs — ship fast, but document and iterate so every test builds on the last.
What should growth and product teams do with this detection?
Don't copy Attio's numbers. Copy the test design. If you're planning a pricing experiment this quarter, bundle a feature-limit variable with your price variable instead of testing price in isolation — you'll learn more per test cycle. And build a monitoring habit: if you don't know what your own pricing page looked like last week, you can't tell your board whether last month's ARR shift was seasonality or a self-inflicted pricing change nobody flagged in standup.
Common questions
Is Attio actually running an A/B test on pricing, or could this be a bug?
It's a test, not a bug. The page structure, layout, and branding were identical across both Safari sessions — only the price points and specific feature-table rows differed. Rendering artifacts don't consistently produce two complete, internally coherent pricing tables. This pattern matches a controlled experiment.
What's the actual price difference between the two variants?
Plus plan tested at $29 versus $35, and Pro plan tested at $69 versus $79. That's roughly a 20% spread on Plus and a 15% spread on Pro — large enough to matter for revenue per seat but not so extreme it risks alienating buyers outright.
Why would Attio vary feature limits like "Seats" and "MCP server" access instead of just price?
Testing feature limits alongside price lets Attio measure willingness-to-pay against actual value delivered, not just a number. A $29 plan without MCP server access and a $35 plan with it are two different products, which gives cleaner signal on what buyers value most.
How confident is ABWatcher that this is a genuine test?
Our analyst confidence is 85%, based on a week-over-week structural and pricing diff on the same URL in the same browser. That threshold reflects strong but not certain evidence — enough to flag it, not enough to claim we know which variant is the eventual winner.
What should other SaaS pricing teams take away from this?
Bundle your test variables. Testing price and feature allowance together, with clean event tracking to decompose which lever moved the needle, gets you more signal per experiment cycle than sequential single-variable tests — especially if your sales cycle is long enough that you can't afford to run five separate tests in a row.
Read next
More from the ABWatcher blog
Nov 22, 2026
Snake River Farms Tests a $25-Off Popup on Its Ad Landing Page
We caught Snake River Farms split-testing an email-capture form and $25-off modal on its landing page. Here's the math on what it would take to call a winner.
Nov 21, 2026
Snake River Farms Tests Mid-Page Email Capture on Its Ad Landing Page
SRF is A/B testing a mid-page lead-capture block and a $25-off popup against a simpler hero-only promo banner on its paid landing page, detected 2024 week-over-week.
Nov 20, 2026
Attio Is Testing a New Tier, Higher Prices, and a New Pitch
Attio is running a live pricing page test with a new $1,000 "Ultra" tier, higher Plus/Pro prices, and a new headline — here's what we caught and what it means.
Nov 19, 2026
Found Quietly Tested a 25% Price Cut on Its Pricing Page
We caught Found running a live pricing A/B test with an annual billing toggle that drops Found Plus from $35 to $26.25/mo. Here's what changed and why it matters.
Nov 8, 2026
Astro Proves "Zero Lock-In" With a Live Code Demo, Not a Claim
Astro's homepage replaces a trust badge row with a working, clickable framework demo — here's the hierarchy and interaction design behind it, detected 60% rare on astro.build.
Nov 7, 2026
Basecamp's Big Numbers: Why Hyper-Precise Stats Beat Vague Social Proof
Basecamp's homepage swaps "trusted by thousands" for 1.7 billion to-dos and 5 petabytes of data. We break down why precision beats vagueness as social proof — and how to test it.
From the glossary
Vocabulary the article uses. See all terms →
- Shrinkage Estimator— A statistical adjustment that pulls noisy per-variant or per-segment estimates toward an overall average to reduce overfitting to randomness.
- Flicker Test— A diagnostic check to confirm whether users briefly see the original page before a variant renders in client-side experiments.
- Pre-Experiment Bucketing Audit— A review process confirming users are being randomly and evenly assigned to experiment variants before launch.
- Above-Fold Exclusion Rule— A test-design rule that deliberately prevents changes to above-the-fold elements so an experiment isolates below-the-fold effects.
- Flicker-Free Testing— A technical setup that prevents users from briefly seeing the original page before a test variant loads.
- Orthogonal Test Design— A test structure where multiple variables are changed independently so their individual effects can be measured without interference.
See more like this
ABWatcher catches A/B tests like this across 1,000+ brands.
Watch live experiments at 1,000+ high-converting brands, complete with hypothesis and takeaway. 7 days of Pro, free, no card, then Free forever for ten watched companies.