
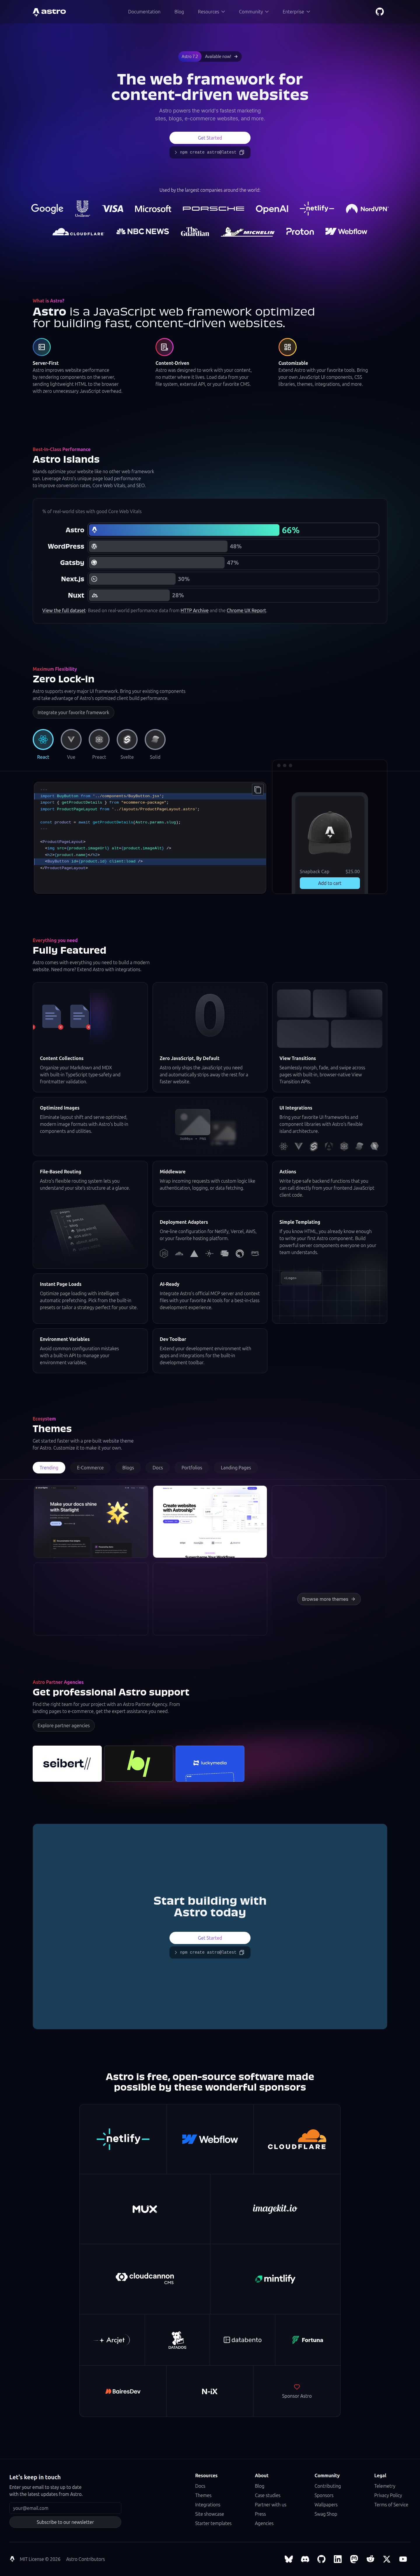
Astro's Homepage Flex: Naming Competitors in a Bar Chart
Astro's homepage now shows a bar chart beating WordPress, Gatsby, Next.js, and Nuxt on Core Web Vitals — with cited data. Here's why naming competitors works.
Diego Hernandez
Growth Marketer · · Updated
TL;DR
- Detected on astro.build homepage, layout surface, social proof category.
- Astro shows 66% of real-world sites with good Core Web Vitals — highest of the group.
- WordPress comes in at 48%, Gatsby at 47%, Next.js at 30%, Nuxt at 28%.
- Data sourced and cited from HTTP Archive and the Chrome UX Report (CrUX).
- Rarity score: 75% — this pattern almost never shows up on public marketing sites.
- Importance score: 60% — direct competitor naming is a high-conviction move, not a filler widget.
What did Astro actually ship?
Astro put a live-style bar chart on its homepage that names four competitors by name and ranks them on real performance data.
The evidence is blunt: "% of real-world sites with good Core Web Vitals — Astro 66%, WordPress 48%, Gatsby 47%, Next.js 30%, Nuxt 28%." No hedging, no "up to," no asterisk-laden footnote burying the source three scrolls down. It's cited inline to HTTP Archive and CrUX — datasets any engineer on the visiting team can go verify themselves.
This isn't a vague "blazing fast" badge. It's a scoreboard. And Astro put itself in first place, in public, next to the exact frameworks its buyers are actively comparing it against.
Why is naming competitors directly still so rare?
Most B2B and dev-tool sites dodge direct comparison because legal and brand teams flinch at naming names. Astro's chart proves that discomfort is often just habit, not a hard rule.
Look at the category most companies default to instead: generic trust badges, "loved by developers" quote carousels, logo walls. Safe. Forgettable. Zero information density. Astro's chart is the opposite — it's a claim you can fact-check in five minutes, which paradoxically makes it more persuasive, not less.
This tracks with what Unbounce's CRO research calls the core of a strong value prop: visitors should think "this was made specifically for someone like me." A developer evaluating static site generators doesn't want "trusted by thousands." They want the CrUX number for the exact five frameworks on their shortlist. Astro gave them precisely that.
How does this fit the rest of the CRO playbook?
The chart works because it stacks three CRO fundamentals that usually get treated as separate tactics: social proof, page speed messaging, and interactivity.
Contentsquare's guide to landing page optimization stresses running controlled experiments on specific page elements rather than guessing. A bar chart with a defensible data source is exactly the kind of element you can iterate on — swap the metric, update the framework list, refresh the data quarter over quarter — without touching anything else on the page.
It also nails the "make it interactive" advice from Heyflow's landing page research: a static claim gets skimmed, a chart gets studied. Visitors linger on visual data longer than they linger on paragraph copy, and every extra second of attention on a proof point is a second closer to conversion.
What's the actual detection data?
Here's the breakdown as it appeared on the page, ranked highest to lowest:
| Framework | % sites with good Core Web Vitals |
|---|---|
| Astro | 66% |
| WordPress | 48% |
| Gatsby | 47% |
| Next.js | 30% |
| Nuxt | 28% |
Detected as a home-page layout change under the social_proof category, with a rarity score of 75% and importance score of 60%. The high rarity number matters more than it looks — most social proof detections we log are logo swaps or testimonial rotations. A cited, competitor-named performance benchmark is a structurally different move, and we don't see it often across the 1,000+ sites we monitor daily.
Should other teams copy this?
Only if the number is real and defensible — otherwise it backfires hard.
The entire mechanism here depends on the data being third-party, sourced, and checkable. If Astro had used an internal benchmark or a cherry-picked test, the chart becomes a liability instead of an asset. Skeptical technical buyers — which is exactly who's evaluating a static site framework — will screenshot it and post it if the numbers don't hold up.
If your product has a legitimately strong, independently verifiable metric against named competitors, this is a high-leverage test to run. If you don't, don't fake it — go build the case study or the benchmark first, then ship the chart. This is also consistent with the basics in Atomix's CRO guide: trust elements only work when they're specific and verifiable, not decorative.
Common questions
What exactly did Astro change on its homepage?
Astro added a bar chart comparing itself against WordPress, Gatsby, Next.js, and Nuxt on the percentage of real-world sites passing Core Web Vitals, citing HTTP Archive and CrUX as the data source, detected on the home page layout.
Why is this considered a rare CRO pattern?
Most social proof widgets use vague claims, logo walls, or testimonials. Directly naming competitors with cited third-party performance data is uncommon — ABWatcher scored this detection at 75% rarity across 1,000+ monitored high-converting sites.
Is naming competitors directly risky for a marketing page?
Yes, if the data isn't verifiable or sourced. It works for Astro because HTTP Archive and CrUX are public, checkable datasets. Without a credible source, direct competitor comparisons can damage trust faster than they build it.
What's the difference between this and typical social proof sections?
Typical social proof is generic — logos, star ratings, quote carousels. This detection is a specific, numeric, sourced comparison against named competitors on a metric (Core Web Vitals) that Astro's exact buyer persona cares deeply about.
Can smaller brands run a similar test?
Yes, if you have a real, sourced advantage on a metric your buyers already track. Start with one credible data point against one named competitor rather than a five-way chart — validate the reaction before expanding it.
The takeaway for your sprint
If you've got a real, sourced number that beats a named competitor on a metric your buyer already cares about, stop hiding it in a footnote. Build the chart, cite the source, put it above the fold. Vague trust badges are free to ignore. Specific, checkable numbers are not.
Read next
More from the ABWatcher blog
Nov 22, 2026
Snake River Farms Tests a $25-Off Popup on Its Ad Landing Page
We caught Snake River Farms split-testing an email-capture form and $25-off modal on its landing page. Here's the math on what it would take to call a winner.
Nov 21, 2026
Snake River Farms Tests Mid-Page Email Capture on Its Ad Landing Page
SRF is A/B testing a mid-page lead-capture block and a $25-off popup against a simpler hero-only promo banner on its paid landing page, detected 2024 week-over-week.
Nov 20, 2026
Attio Is Testing a New Tier, Higher Prices, and a New Pitch
Attio is running a live pricing page test with a new $1,000 "Ultra" tier, higher Plus/Pro prices, and a new headline — here's what we caught and what it means.
Nov 19, 2026
Found Quietly Tested a 25% Price Cut on Its Pricing Page
We caught Found running a live pricing A/B test with an annual billing toggle that drops Found Plus from $35 to $26.25/mo. Here's what changed and why it matters.
Nov 8, 2026
Astro Proves "Zero Lock-In" With a Live Code Demo, Not a Claim
Astro's homepage replaces a trust badge row with a working, clickable framework demo — here's the hierarchy and interaction design behind it, detected 60% rare on astro.build.
Nov 7, 2026
Basecamp's Big Numbers: Why Hyper-Precise Stats Beat Vague Social Proof
Basecamp's homepage swaps "trusted by thousands" for 1.7 billion to-dos and 5 petabytes of data. We break down why precision beats vagueness as social proof — and how to test it.
From the glossary
Vocabulary the article uses. See all terms →
- Shrinkage Estimator— A statistical adjustment that pulls noisy per-variant or per-segment estimates toward an overall average to reduce overfitting to randomness.
- Flicker Test— A diagnostic check to confirm whether users briefly see the original page before a variant renders in client-side experiments.
- Pre-Experiment Bucketing Audit— A review process confirming users are being randomly and evenly assigned to experiment variants before launch.
- Above-Fold Exclusion Rule— A test-design rule that deliberately prevents changes to above-the-fold elements so an experiment isolates below-the-fold effects.
- Flicker-Free Testing— A technical setup that prevents users from briefly seeing the original page before a test variant loads.
- Orthogonal Test Design— A test structure where multiple variables are changed independently so their individual effects can be measured without interference.
See more like this
ABWatcher catches A/B tests like this across 1,000+ brands.
Watch live experiments at 1,000+ high-converting brands, complete with hypothesis and takeaway. 7 days of Pro, free, no card, then Free forever for ten watched companies.